Amazon Bedrock adds explicit prompt caching for open-weight models
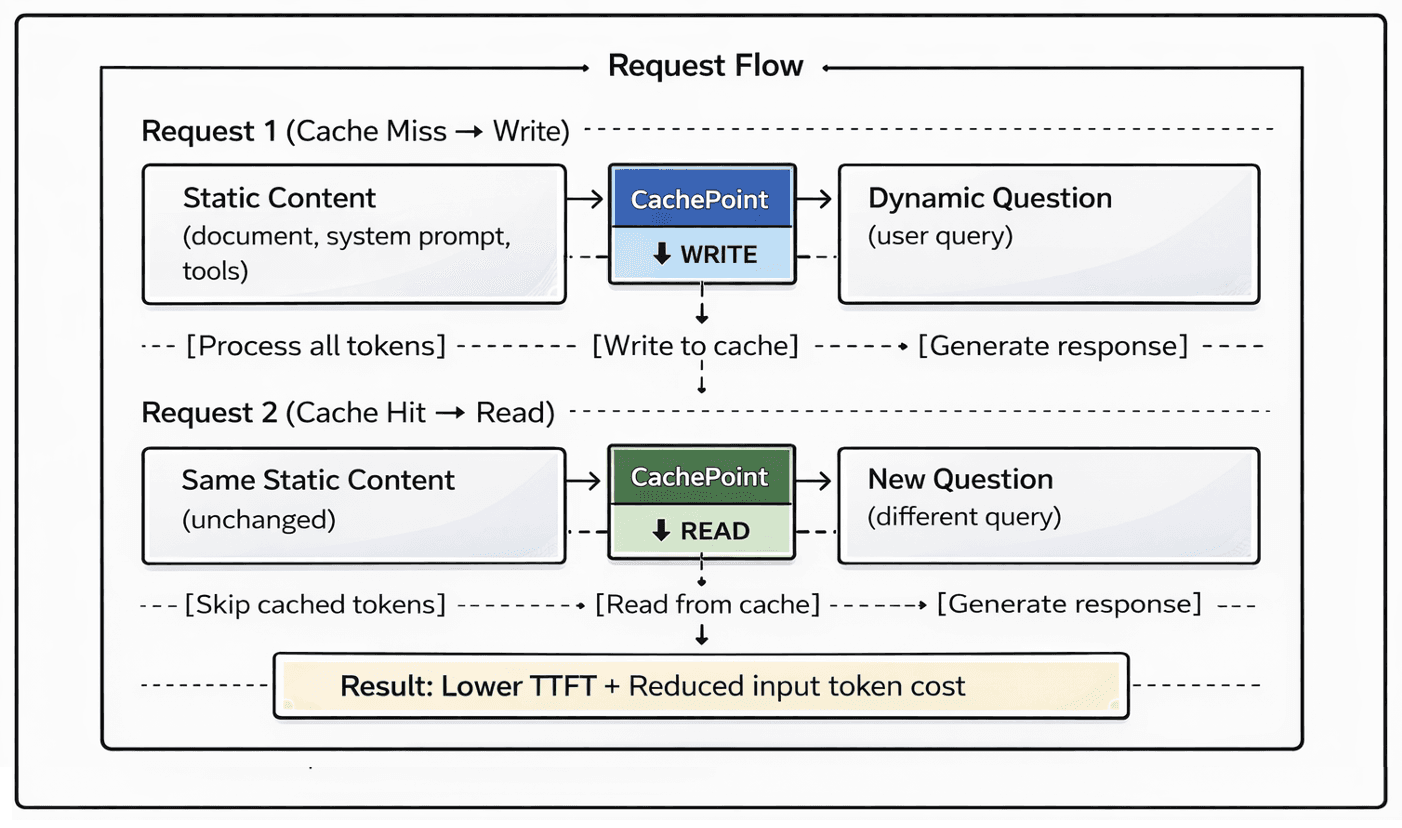
Amazon Bedrock now supports explicit prompt caching for open-weight models, allowing developers to reuse long context across requests to reduce input costs and latency. The feature works alongside implicit caching and is available through the Chat Completions API. Cache reads are billed at lower rates than standard input, with savings scaling as prefixes are reused more frequently.
TL;DR
- Open-weight models on Amazon Bedrock now support explicit prompt caching via Chat Completions API
- Explicit caching lets developers mark reusable content prefixes with prompt_cache_breakpoint markers
- Cache reads cost less than standard input, with savings growing as prefixes are reused
- Implicit caching also available, automatically reusing eligible prefixes on a best-effort basis
Why It Matters
Prompt caching addresses a real cost and performance problem in generative AI applications that repeatedly send the same long context, such as system prompts, reference documents, or conversation history. By reading cached prefixes instead of reprocessing them, applications can significantly reduce both input costs and response latency. This is particularly valuable for agent loops and multi-turn conversations where context is stable across requests.
Business Impact
For organizations running generative AI applications at scale, prompt caching directly reduces operational costs through lower input token billing and improves user experience through faster response times. The feature is especially relevant for use cases like coding agents, document analysis, and conversational systems where the same context is sent repeatedly. Cost savings compound as reuse frequency increases.
Key Implications
- Developers can choose between implicit caching (automatic, best-effort) or explicit caching (controlled via breakpoint markers) depending on their use case and need for precision
- Organizations with high-volume, repetitive AI workloads can achieve measurable cost reductions without application redesign
- Data privacy is maintained, as prompts and outputs are not shared with model providers or used for training
What to Watch
Monitor adoption patterns across different open-weight models on Bedrock to understand which use cases benefit most from caching. Watch for updates to minimum prefix lengths, cache retention periods, and pricing structures across models, as these factors directly impact the ROI of caching implementations. Track whether other cloud providers introduce similar features and how pricing evolves.
Subscribe to the newsletter
The latest stories and analysis, delivered to your inbox.
Free. No spam. Unsubscribe any time.


