VFF - The signal in the noise
News

PrismML Bets on Compact LLMs to Reshape AI Deployment

Read original
Share
PrismML Bets on Compact LLMs to Reshape AI Deployment

PrismML, an AI lab, is developing a compact large language model intended to shift how AI is deployed and used. The article positions PrismML as an emerging player worth attention in the AI space, though specific technical details, capabilities, or business model are not provided in the source material.

  • PrismML is an AI lab working on a small-scale LLM
  • The company aims to change how AI is adopted and deployed
  • PrismML is positioned as an emerging player in the AI sector
  • Specific technical capabilities or launch timeline not detailed in source

Smaller, more efficient language models could democratize AI access and reduce computational barriers to deployment. If PrismML succeeds in making a viable compact LLM, it could influence how enterprises and developers approach AI integration.

Compact LLMs reduce infrastructure costs and enable deployment in resource-constrained environments, potentially opening new markets for AI applications. Success here could shift competitive dynamics away from scale-dependent models toward efficiency-focused alternatives.

  • Smaller models may lower barriers to entry for organizations with limited compute budgets
  • Efficiency-focused approaches could challenge the current paradigm of ever-larger foundation models
  • Deployment flexibility could expand AI use cases in edge computing and on-device scenarios

Monitor PrismML's technical announcements, model performance benchmarks, and adoption by early customers. Track whether compact LLMs gain traction as a category and how established AI companies respond to efficiency-focused competition.

OneUpAI
OneUp Your Business. Get More Done. OneUp Your Business. Get More Done. OneUp Your Business. Get More Done.
Learn More
Share

Subscribe to the newsletter

The latest stories and analysis, delivered to your inbox.

Free. No spam. Unsubscribe any time.

Related stories

Vera Rubin NVL72 Debuts With 3.7x Throughput Gain Over GB300
Research

Vera Rubin NVL72 Debuts With 3.7x Throughput Gain Over GB300

NVIDIA's Vera Rubin NVL72 system achieved leading performance in its MLPerf Inference v6.1 debut, delivering up to 3.7x higher throughput than the GB300 NVL72 on Qwen3-VL and up to 2.5x on DeepSeek-R1. The results demonstrate the effectiveness of full-stack hardware and software codesign, including enhanced Tensor Cores, NVFP4 precision, and disaggregated serving techniques. A 288-GPU submission across four GB300 NVL72 racks achieved 99% scaling efficiency, and software optimizations alone delivered up to 1.6x performance gains from v6.0 to v6.1.

by Zhihan Jiang· NVIDIA Blog (AI)
Lightweight dual-model agents show promise for autonomous materials research
Research

Lightweight dual-model agents show promise for autonomous materials research

Researchers at Nature Machine Intelligence have demonstrated a dual-model architecture for autonomous crystal materials research using two lightweight large language models working collaboratively. The approach combines reasoning and scientific tool execution while maintaining computational efficiency and local deployability. The method achieves competitive performance without requiring expensive infrastructure, making advanced materials research more accessible.

by Tongyu Shi· Nature Machine Intelligence
Perplexity deploys GPT-6 Astra to autonomous production systems
News

Perplexity deploys GPT-6 Astra to autonomous production systems

Perplexity is deploying OpenAI's GPT-6 Astra model to handle end-to-end system operations, including writing communications, modifying software, and monitoring production infrastructure. The company reports significantly reduced oversight requirements compared to earlier models. This represents a shift toward autonomous AI management of critical business systems.

· OpenAI
Alibaba Open-Sources Qwen3.8 Trillion-Parameter Model
News

Alibaba Open-Sources Qwen3.8 Trillion-Parameter Model

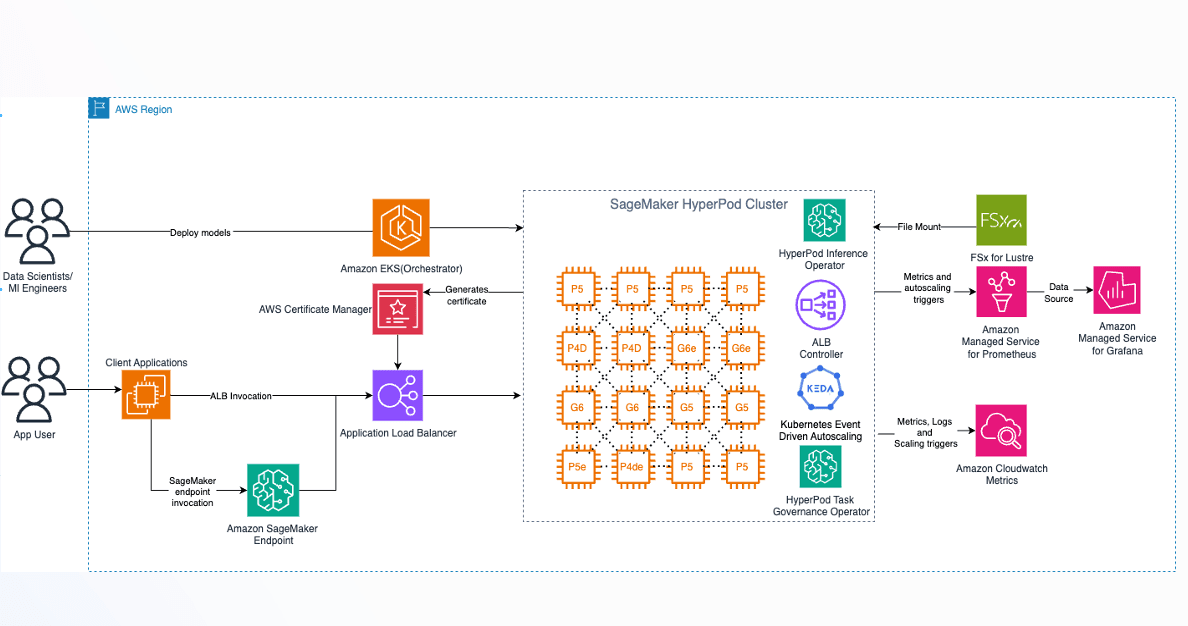
Alibaba released Qwen3.8-2.4T-A95B as open weights on August 12, 2026, marking the first time a Qwen-Max-class model became publicly available. The 2.4 trillion parameter model uses a hybrid linear-plus-full-attention architecture with 95 billion activated parameters per token and supports up to 262K native context tokens, extensible to 1M. AWS published a deployment guide showing how to run the model on SageMaker HyperPod using vLLM on ml.p6-b300 instances with NVIDIA B300 Blackwell Ultra GPUs.

by Dmitry Soldatkin· AWS Machine Learning Blog